Contextual Drag - How Errors in the Context Affect LLM Reasoning
Abstract
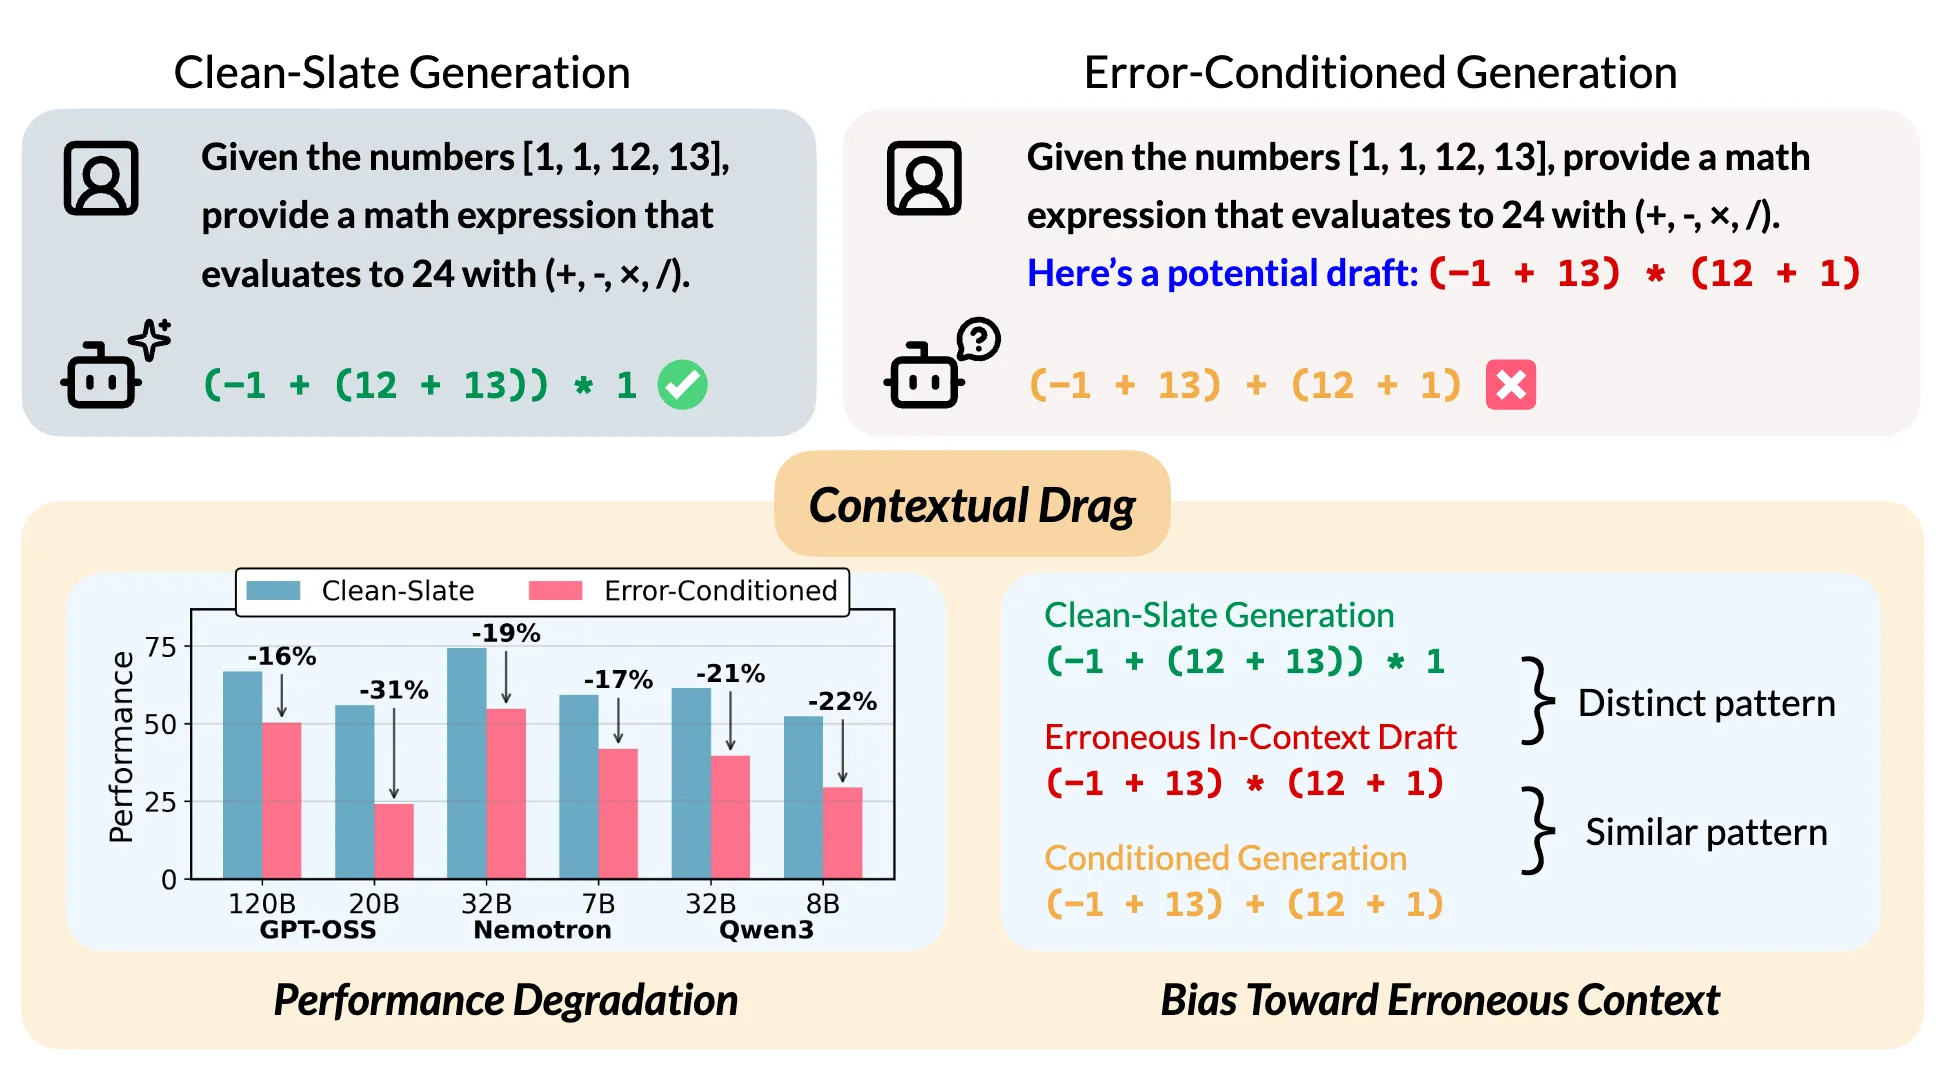
Central to many self-improvement pipelines for large language models (LLMs) is the assumption that models can improve by reflecting on past mistakes. We study a phenomenon termed contextual drag - the presence of failed attempts in the context biases subsequent generations toward structurally similar errors. Across evaluations of 11 proprietary and open-weight models on 8 reasoning tasks, contextual drag induces 10-20% performance drops, and iterative self-refinement in models with severe contextual drag can collapse into self-deterioration. Structural analysis using tree edit distance reveals that subsequent reasoning trajectories inherit structurally similar error patterns from the context. We demonstrate that neither external feedback nor successful self-verification suffices to eliminate this effect. While mitigation strategies such as fallback-behavior fine-tuning and context denoising yield partial improvements, they fail to fully restore baseline performance, positioning contextual drag as a persistent failure mode in current reasoning architectures.
Citation
@misc{cheng_contextual_drag_2026,
  author    = {Cheng, Yun and Zhu, Xingyu and Zhao, Haoyu and Arora, Sanjeev},
  doi       = {10.48550/arXiv.2602.04288},
  month     = {February},
  publisher = {arXiv},
  title     = {Contextual Drag: How Errors in the Context Affect LLM Reasoning},
  url       = {https://arxiv.org/abs/2602.04288},
  year      = {2026}
}