T²MLR: Transformer with Temporal Middle-Layer Recurrence
* Equal contribution
Abstract
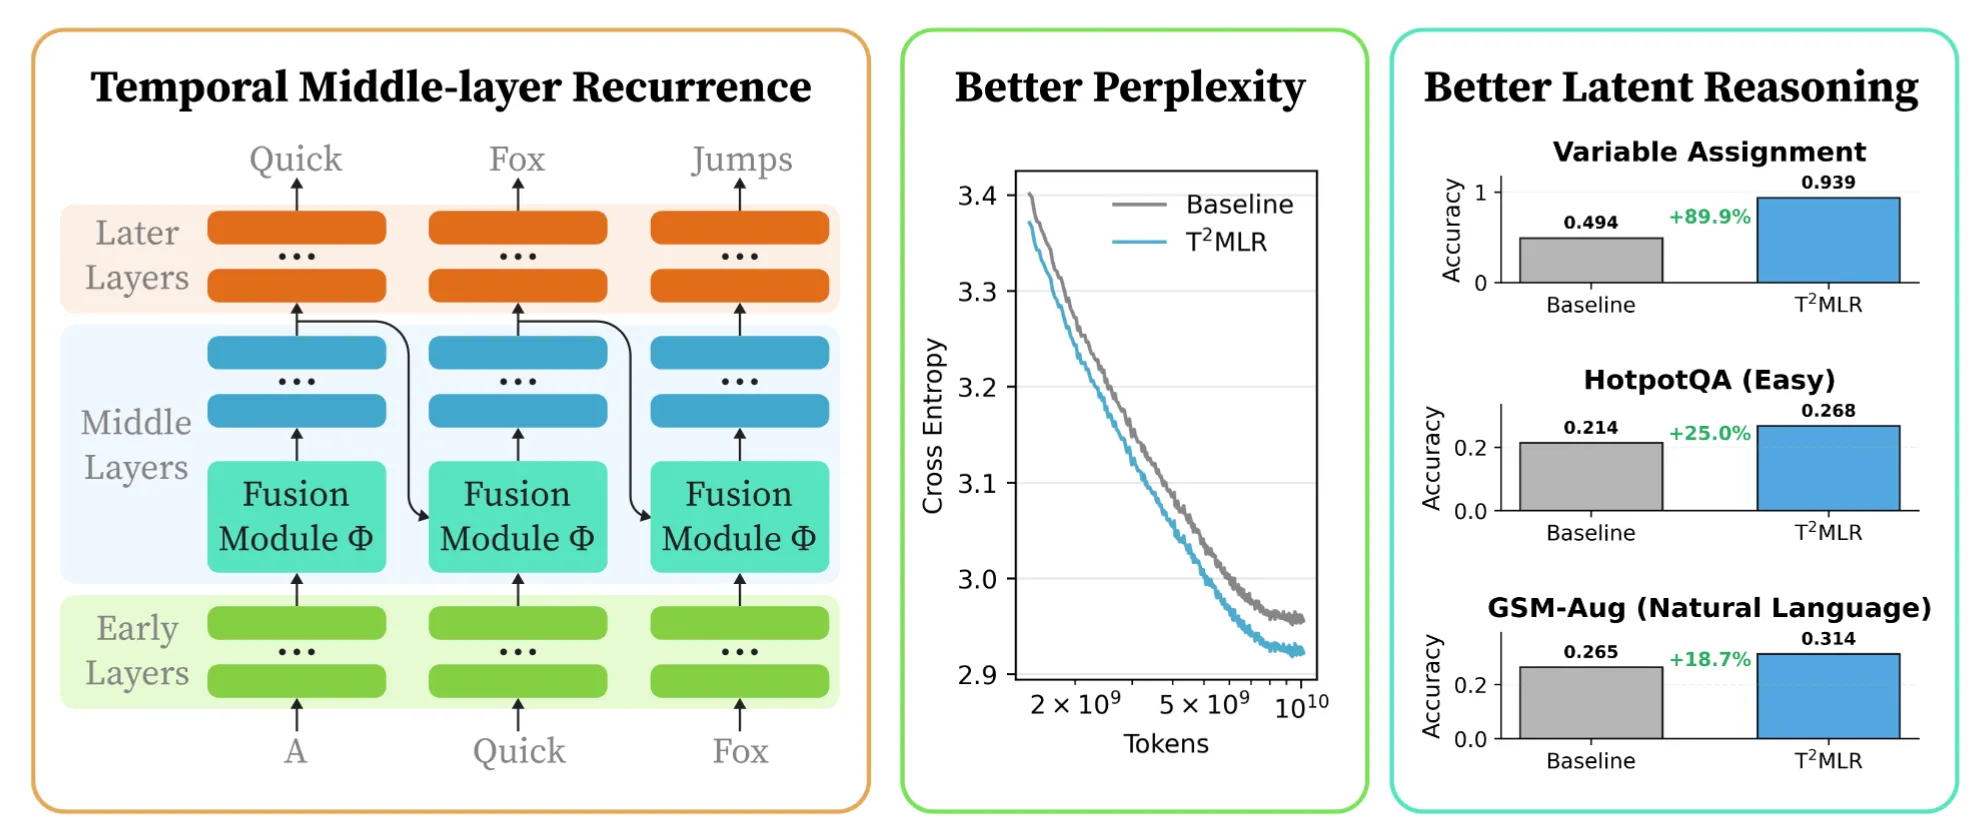
We introduce Transformers with Temporal Middle-Layer Recurrence (T²MLR), a generalized Transformer architecture that integrates attention and recurrence by routing a lightweight temporal pathway through the middle layers. Motivated by latent-reasoning and looped-Transformer lines of work, T²MLR injects intermediate representations from deeper layers of the previous token into earlier layers of the current token via a gated recurrent pathway, enabling iterative latent computation while preserving dense, token-level supervision. Across natural-language pretraining and multi-hop reasoning finetuning, T²MLR consistently outperforms parameter-matched Transformer baselines at the same inference compute. Moreover, we find that looping only a middle-layer block (as little as 20% of all layers) often outperforms full-layer looping. This offers a new perspective on latent reasoning in Transformers - effective iterative refinement does not necessarily require full-stack recurrence. It can instead be achieved more effectively through targeted middle-layer recurrence.
Citation
@inproceedings{cai_t2mlr_2026,
  author    = {Cai, Ziyang and Zhu, Xingyu and Dong, Yihe and He, Yinghui and Arora, Sanjeev},
  booktitle = {LIT Workshop @ ICLR 2026},
  title     = {T$^2$MLR: Transformer with Temporal Middle-Layer Recurrence},
  url       = {https://openreview.net/forum?id=fQbk1EQWBO},
  year      = {2026}
}